How to / It will not open, or it opened wrong
What is ANSEL, and why your names look wrong
Your file says 1 CHAR ANSEL and the accents came out as separate marks. ANSEL puts the accent before the letter, and Unicode puts it after.
Intermediate15 minutesChecked against the tools on 6 Sep 2026Uses Encoding Repair and File Inspector
what-is-ansel-and-why-your-names-look-wrong.md, 9,252 characters. The same bytes answer at /how-to/what-is-ansel-and-why-your-names-look-wrong.md.
Your file's header carries the line 1 CHAR ANSEL. Somewhere a name that should read Zoë reads Zoèe, or Müller reads Mèuller, or every accented letter has turned into a letter followed by a stray mark.
ANSEL is a library character set used in older GEDCOM exports. A reader that uses the wrong decoder can display its accent bytes as extra letters.
The pages that come up when you search for it are a Haskell library, a mirror of the specification, a university page from the 1990s and an archiveteam entry. All accurate, none written for someone looking at a wrong name.
What causes the mangling
ANSEL is ANSI Z39.47, built for American library catalogue cards. It holds 8-bit values: the first 128 are plain ASCII, and the rest are letters and marks a librarian needed for European and transliterated names.
The part that surprises people is where the accent goes.
In ANSEL a diacritic is its own byte, and that byte comes before the letter it sits on. ë is two bytes: E8 for the umlaut, then 65 for the letter e. In Unicode the same combination is written the other way round: U+0065 for the e, then U+0308 for the combining umlaut. Mark first in ANSEL, letter first in Unicode.
The following examples show what happens when a reader interprets ANSEL bytes as Windows-1252:
| Written in ANSEL as | Bytes | Read as ANSEL | Read as Windows-1252 |
|---|---|---|---|
Zoë | 5A 6F E8 65 | Zoë | Zoèe |
Müller | 4D E8 75 6C 6C 65 72 | Müller | Mèuller |
À | E1 41 | À | áA |
å | EA 61 | å | êa |
Compare the third and fourth columns. In these examples, a Windows-1252 reader interprets the accent byte as a separate letter and leaves the base letter beside it. Other ANSEL bytes produce different errors.
Two more ANSEL facts worth knowing before repairing anything.
Some ANSEL bytes are complete letters, not marks. A2 is Ø and B2 is ø; A5 is Æ and B9 is £. Read as Windows-1252 those four become ¢, ², ¥ and ¹: one wrong character rather than a pair, so a name with an Ø in it looks less broken and is just as wrong.
GEDCOM's ANSEL includes additional values at BE, BF, CD, CE and CF. A decoder needs those GEDCOM mappings to interpret them.

Diagram source
flowchart TD
  H["Header says 1 CHAR ANSEL"] --> R["Encoding Repair: read the verdict block"]
  R --> Q{"HEAD.CHAR says versus Bytes are"}
  Q -- "both ANSEL" --> T["Review decoded names, then transcode to UTF-8"]
  Q -- "says ANSEL, bytes are Windows-1252" --> M["Reinterpretation: every non-ASCII value re-read"]
  Q -- "says ANSEL, bytes hold UTF-8 written twice" --> D["Double encoding: reversed row by row"]
  T --> N{"Compose accents into single letters?"}
  N -- "on" --> C["ö as one character U+00F6"]
  N -- "off" --> S["o plus combining mark, as the source wrote it"]
The repair
Numbers below are from fixtures/public/TGC551.ged, a 67,316-byte (about 66 KiB) ANSEL test file in GEDCOM 5.5, with NFC left off.
- Open File Inspector and drop the file. Read Header. On this fixture GEDCOM version reads
5.5, Producer readsGEDitCOM 2.9.4, Declared charset readsANSELand Decoded as readsansel. The version alone does not identify the bytes' charset.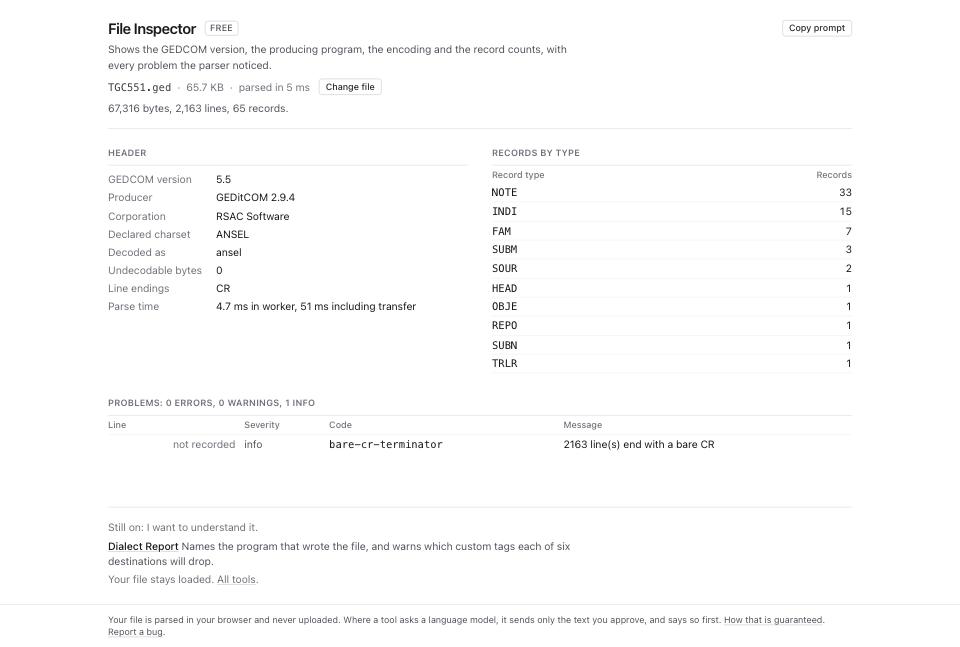
- Open Encoding Repair and drop the same file. The header line reads
156 values with non-ASCII text, no value needs a correction. 156 values keep the same text but are written with different bytes as ANSEL becomes UTF-8. - Read the verdict block. HEAD.CHAR says, Parser read it as and Bytes are all read
ANSELon this fixture. Agreement supports a transcode, but the detector is heuristic. Compare decoded names against records you trust. - Open How the charset was decided (6 candidates scored). On this fixture ANSEL wins at 70% confidence, and its rationale counts
289 composing marksand1219 unusual marksagainst Windows-1252's729 accented lowercase before a capital. A high composing-mark count is the signature of ANSEL: those bytes are accents standing before their letters.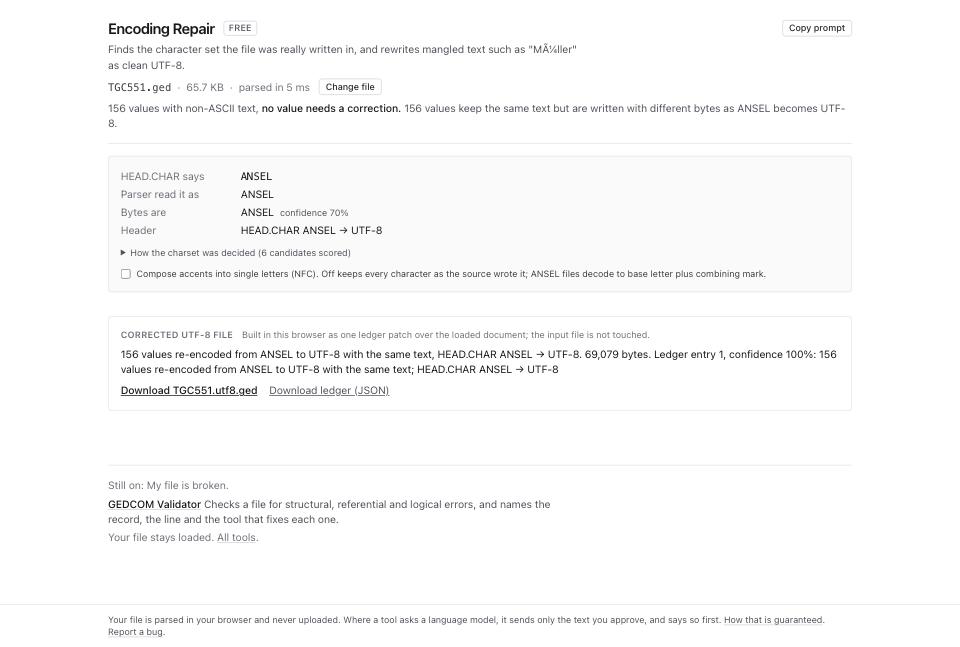
- Read Header, the last row of the verdict block. It states the header change the repair will make. On this fixture it reads
HEAD.CHAR ANSEL → UTF-8. - Choose Compose accents into single letters (NFC) before reviewing corrections. It starts off. Ticked,
oplus combining umlaut becomesö; off, the decoded sequence stays decomposed. Select it according to the destination's requirements. Changing NFC resets correction selections and changes this example's counts and output size. - Look for Corrections. With NFC off, this fixture needs no value corrections. When proposals exist, the table previews the first 400 with Before, After and confidence. Proposals start accepted, and Accept all and Reject all affect undisplayed rows too. Rejecting a correction can still transcode the decoded value.
- Read Corrected UTF-8 file. At 5,000 corrections or fewer, the page builds output on load. With NFC off, this fixture reports
156 values re-encoded from ANSEL to UTF-8 with the same text, HEAD.CHAR ANSEL → UTF-8. 69,079 bytes. Ledger entry 1, confidence 100%. Above 5,000 corrections, press Apply N changes and build file after review. The ledger confidence does not prove the detector chose the correct charset. - Click the download link, named after your file. On this fixture it reads Download TGC551.utf8.ged.
- Click Download ledger (JSON) as well if you want the machine-readable record of every change.
What to check when it worked
- The repaired file's header carries
1 CHAR UTF-8. Run File Inspector on it and read the charset line. - Open the repaired file in GEDCOM Viewer and search for a name you know has an accent. It reads as one accented letter, not a letter with a mark standing beside it.
- Encoding Repair on the repaired file reports
Nothing to change: the file is UTF-8 with a matching header. - The value count matches. On this fixture 156 values held non-ASCII text before the repair and 156 carry the same text afterwards.
- Check the original for
undefined-ansel-byte. Such a finding means the decoder used a private-use escape for an undefined byte; UTF-8 transcoding does not preserve that byte as its original raw byte.
What to do when it did not
Bytes are reads Windows-1252 while the header says ANSEL. The detector proposes a different interpretation; it has not proved the header wrong. Read Reinterpretation and compare names from different parts of the file before accepting corrections.
Names read Müller rather than Mèuller. That is double encoding, not ANSEL: UTF-8 bytes written a second time through a single-byte table. The verdict block shows a Double encoding row and reverses it. How to fix garbled characters and accents in a GEDCOM covers that case.
Some characters became question marks in the destination program. Compare the original, the downloaded UTF-8 file and the imported result. This separates earlier replacements from destination conversion or display problems. A literal ? no longer identifies the lost character; a missing glyph may only require a suitable font.
You are moving to GEDCOM 7.0. 7.0 removed ANSEL entirely; UTF-8 is the only charset. Repair the encoding first, then read how to convert GEDCOM 5.5.1 to 7.0, and what does not survive.
A byte has no ANSEL meaning at all. File Inspector reports undefined-ansel-byte. The original ANSEL codec can round-trip its private-use escape to the original byte. Encoding Repair instead writes UTF-8, which carries the private-use character as new bytes. Keep the original for recovery and do not treat the escape as a known letter.